
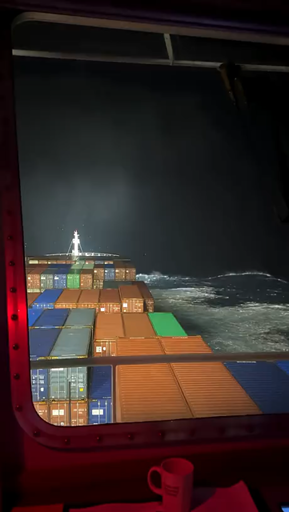
Attached: 1 video
Someone secure the hot pants!!!
Edit: as pointed out in the comments, this might be AI generated. Judge for yourself.
Attached: 1 video
Someone secure the hot pants!!!
Edit: as pointed out in the comments, this might be AI generated. Judge for yourself.
LLMs shit out words, not images
Multimodal ones definitely have image input and output. Gemini Omni can do text/image/video in and video/text out, though generally video models tend to be specialized.
Then it’s not an LLM, it’s several models in a wrapper, although of course the user will be interfacing with the built-in LLM when prompting